How we predict
The science behind anticipating earnings guidance revisions
Most market participants react to guidance changes after they are announced. We built a
system that detects the linguistic fingerprints of an impending revision before the press
release is drafted. First, we ingest thousands of corporate disclosures in real time. Next,
we extract subtle shifts in language that human analysts routinely miss. Finally, we score
the probability of a revision and deliver it to research teams with enough lead time to
think, not just react.
Fully transparent
Every signal includes its linguistic triggers, confidence interval, and reasoning path — no black-box mystery.
Continuously validated
Models are backtested quarterly, retrained monthly, and audited against real outcomes, not simulated success.
Measurable lead time
Signals typically surface one to three weeks before official guidance revisions reach the market.
Three principles that keep our models honest
Fundamental intuition meets machine scale
Experienced analysts know that tone matters, that hedging intensifies before bad news, that precision often signals confidence. We encode this intuition into features that machines can measure at scale — across thousands of companies, every quarter, without fatigue or bias. The result is not a replacement for human judgment but a force multiplier for the patterns analysts already suspect.
Unstructured data deserves structured rigor
Earnings calls, SEC filings, and management presentations are messy. Language is
ambiguous, context-dependent, and full of corporate euphemism. We treat this
unstructured text with the same methodological discipline that quants apply to price
data — defining features, establishing baselines, measuring drift, and validating
signals against ground truth rather than convenient proxies.
Predictive power decays without maintenance
A model that worked last quarter may fail next quarter as language evolves, sectors
rotate, and executives learn to manage narrative expectations. We do not deploy and
forget. Every model is monitored for performance degradation, retrained on fresh data,
and adjusted when real-world outcomes diverge from predictions. Maintenance is not an
afterthought — it is the core of sustainable predictive accuracy.
From raw transcript to ranked signal
A five-stage pipeline that transforms corporate language into actionable foresight, with validation at every step and no stage left unexamined.
1
Ingest and normalize
We collect earnings call transcripts, SEC filings, press releases, and management presentations from multiple sources in real time. Text is cleaned, standardized, and tagged with metadata including company, sector, date, and document type so downstream models operate on consistent inputs.
Coverage spans thousands of companies across North America, Europe, and
Asia-Pacific with daily refresh cycles.
2
Extract linguistic features
Natural language processing identifies hedging patterns, qualifier density, forward-looking statement degradation, sentiment trajectory, and lexical specificity. Each feature is measured relative to a company-specific baseline established over prior quarters, so signals reflect genuine change rather than cross-sectional differences.
Over four hundred engineered features feed into the scoring layer, with
feature importance tracked and reported.
3
Score and validate
Ensemble models rank revision probability by direction, magnitude, and timing.
Each prediction carries a confidence interval calibrated against historical
accuracy. Predictions are backtested, stress-tested, and compared against actual
outcomes to surface model weaknesses before they affect live signals.
Quarterly model audits publish accuracy metrics, coverage gaps, and acknowledged limitations for partner review.
Model evolution
2023
Prototype built
A weekend experiment in parsing earnings call sentiment with off-the-shelf NLP tools produced surprisingly directional results on a small test set.
2023
First backtest
We tested the prototype against five years of guidance revisions and found measurable predictive signal in linguistic features, but also significant false positive rates in cyclical sectors.
2024
Feature engineering
We moved beyond simple sentiment to engineered features measuring hedging intensity, qualifier density shifts, and forward-looking language degradation relative to company baselines.
2024
Live deployment
The first version of the platform went live with coverage of two hundred companies, delivering signals directly to three research partner desks via API and email alerts.
2025
Coverage expansion
We expanded to over three hundred forty companies across three continents, adding Asia-Pacific coverage and multilingual processing for non-English earnings commentary.
2025
Audit framework
We introduced quarterly public model audits documenting accuracy, latency, coverage gaps, and acknowledged limitations — because trust requires verifiable transparency.
2026
Confidence refinements
A rebuilt confidence interval engine now accounts for sector-specific volatility patterns, reducing false positives in cyclical industries and improving signal prioritization.
The people building the prediction engine
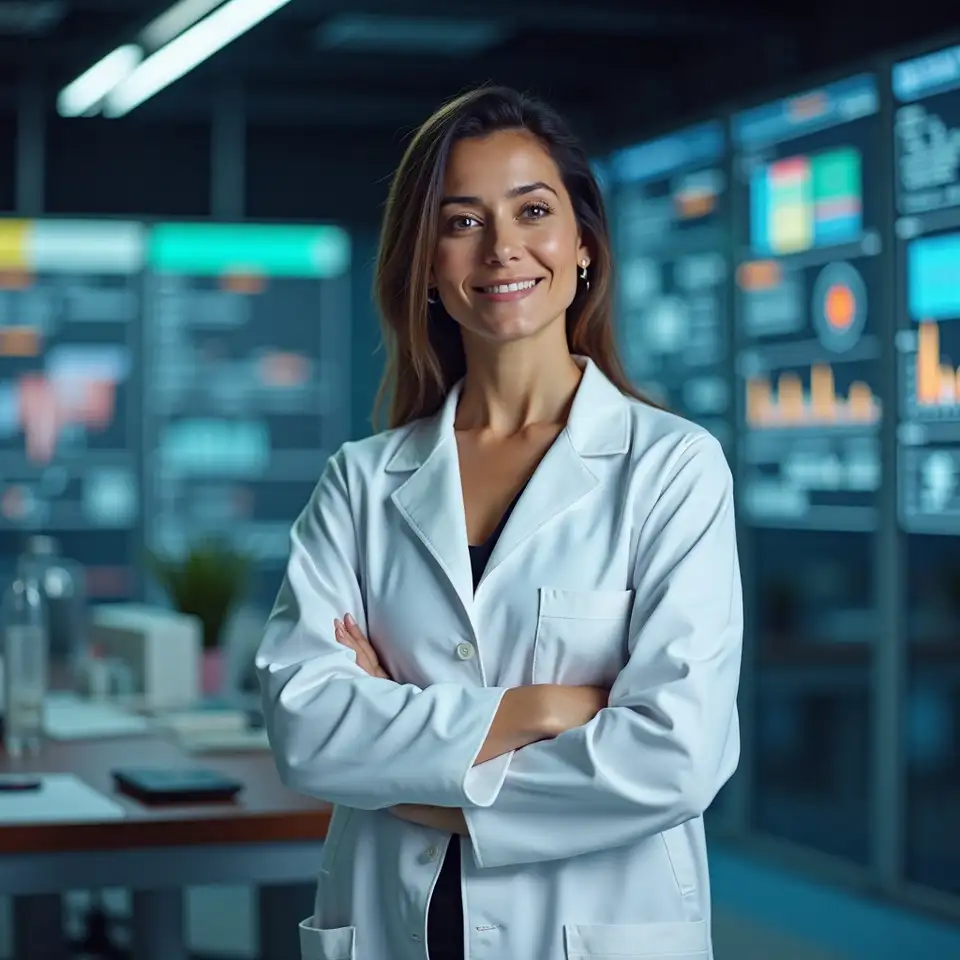
Dr. Elena Vasquez
Lead Research Scientist
Elena spent a decade in computational linguistics before applying her expertise to financial text. She designed the feature extraction pipeline that translates corporate language into measurable signals and insists that every model output include a human-readable reasoning path.
Frequently asked questions
Common questions about how our models work, what they can and cannot do, and how we
validate the signals we deliver to research teams.
Every signal includes a reasoning path showing which linguistic features
shifted, how they compared to the company's historical baseline, and
what confidence interval the model assigned. We do not hide the logic behind
black-box outputs.
We track directional accuracy, lead time, and confidence calibration against
actual guidance revisions. Results are published in quarterly audits that
include both successes and failures, with no selective reporting.
Transcripts and filings are typically ingested within hours of publication. The pipeline refreshes daily, and signals update as new disclosures arrive, so predictions reflect the most recent available language.
Coverage spans over three hundred forty companies across North America,
Europe, and Asia-Pacific, with emphasis on sectors where management
commentary is frequent and guidance revisions are material to valuation.
Models are retrained monthly on fresh data and audited quarterly against real outcomes. When performance degrades in specific sectors, targeted adjustments are made before drift affects live signal quality.
We document false positives, analyze whether the miss was due to model
error, data quality, or genuine unpredictability, and feed those findings
back into feature engineering and training protocols.